COOL AI THING #29 / PREFIX GATEWAY
Not that cash.
Cache.
An AI model already did the work.
Can the next question use it?
I built a gateway for two copies of a small model on my laptop. Then I tried to give it a clickable griffin. Naturally.
Keep the work.
Ask another question.
A model processes text into numbers called keys and values. Keeping those calculations in memory—the KV cache—can let it reuse work from earlier text when it generates what comes next.
That’s different from saving a finished answer. A follow-up still includes the document and conversation, and the model still has to process the new question and produce a fresh answer.
Can the gateway send the request to the copy that can reuse the work?
The two copies run the same model, but each owns its own saved calculations. The gateway’s job is to choose a suitable copy. There’s no second document upload and no transfer of cached calculations between them.
This diagram explains the routing idea. It is not a recording of a new end-to-end routing test.
When can saved work actually be reused?
The new request needs a matching beginning, the same model and compatible saved state that is still available. If the state is missing or incompatible, the model has to do that work again. Two workers also share the laptop’s GPU and memory; this is not a claim of twice the hardware.
A small test.
A visible difference in work.
I asked a couple of questions about a dummy document. In the recorded follow-up, the model reused 1,010 input tokens and processed 16 new input tokens.
Those are counts for one request, not totals across the experiment. The answer used six output tokens; the 16 above is input, not output.
It shows that the local model reused a prefix in that request. It doesn’t, by itself, establish a controlled speedup, prove the whole planned routing comparison, or say anything about your ChatGPT bill.
The recorded setup
- Machine
- Apple M4 MacBook Air · 16 GB unified memory
- Model
- Qwen2.5-1.5B-Instruct · Q4_K_M
- Runtime
- llama.cpp with Metal · two local workers
- Input
- A synthetic document and follow-up questions
- Recorded request
- September 28, 2026 · fb52fe3c
The broader guided session stopped after four requests when its memory safeguard fired. These observations are a bounded local experiment, not a production benchmark.
Then I tried to put
a griffin in ChatGPT.
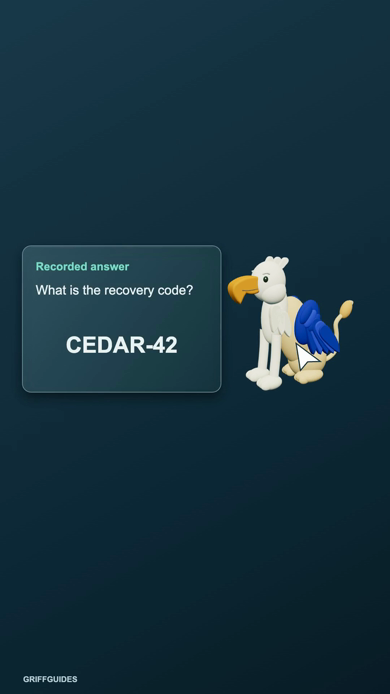
The idea was simple: click a griffin and see an answer beside it. In the animation, that answer is text from the recorded test.
In the actual ChatGPT attempt, it retrieved my recorded test result. The 3D griffin didn’t load.
That’s the honest stopping point. Retrieving the saved result was not a fresh model inference, and it did not demonstrate working interaction with a new document.
See the recorded outcome in the video →Not cash, CACHE.
Cool AI Thing #29: the prefix gateway, the local test, and the attempt to bring a griffin into ChatGPT.
If the player does not load, open the video directly on TikTok.
The experiment is local.
The public package isn’t ready.
The current full installer targets Apple Silicon. Public download packages and support across both macOS architectures have not been verified, so there is no install button here yet.
The explanation and build video
Explore the idea, the one-request token counts and the honest ChatGPT outcome above.
Watch the video →A downloadable demo
A portable recorded demo and a live demo for your own document still need implementation and verification.
For now, this page is the build story. It does not launch a model, connect to your ChatGPT account or upload a document.